Nature Communications 2025
M3FM
Medical Multimodal Multitask Foundation Model for Lung Cancer Screening
Current or former lab member. Select a name to see all of their projects.
Abstract
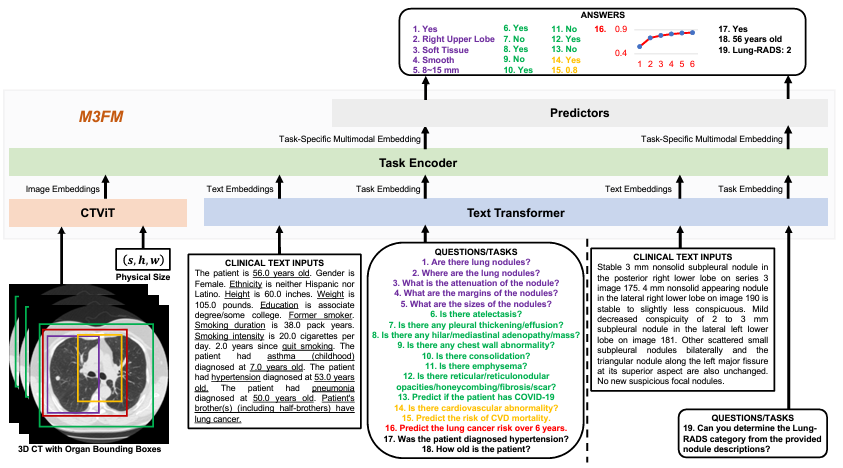
A lung cancer screening exam produces more than images. Each low-dose CT scan comes with demographics, smoking history, disease history and radiology reports. M3FM (medical multimodal-multitask foundation model) is built to use all of this at once. It takes a 3D CT volume, free-text clinical data and a task written as a plain-language question, and returns the answer.
The model has four parts: a CT Vision Transformer (CTViT) that encodes CT volumes at multiple scales, a Text Transformer for clinical text and questions, a Task Encoder that fuses them into a task-specific multimodal embedding, and lightweight Predictors. It was trained on a curated dataset covering 49 types of clinical data, 163,725 chest CT series and 17 screening-related tasks, from lung nodule characterization and Lung-RADS categorization to lung cancer risk and cardiovascular disease mortality risk.
Compared with previous state-of-the-art models, M3FM improves lung cancer risk prediction by up to 20% and cardiovascular disease mortality risk prediction by up to 10%. It also works with different combinations of input data, identifies the data elements that inform a prediction, and adapts to new out-of-distribution tasks from a small dataset.
What’s in the repository
- Model definitions: CTViT, Text Transformer, Task Encoder and Predictors
- An inference API with configurations for six-year lung cancer risk and cardiovascular abnormality prediction
- Two demo cases from the NLST dataset, and a notebook that draws relevance maps on the CT volume and the clinical text
Citation
@article{niu2025m3fm,
  title   = {Medical multimodal multitask foundation model for lung cancer screening},
  author  = {Niu, Chuang and Lyu, Qing and Carothers, Christopher D. and Kaviani, Parisa and Tan, Josh and Yan, Pingkun and Kalra, Mannudeep K. and Whitlow, Christopher T. and Wang, Ge},
  journal = {Nature Communications},
  volume  = {16},
  pages   = {1523},
  year    = {2025},
  doi     = {10.1038/s41467-025-56822-w}
}